Reliability and Robustness
The reliability and robustness of Orchestra is mainly based on the internal queuing engine. Typical two category of errors has to be differentiated. The first category are technical errors ( e.g. network errors) that can be solved by re-executing workitems. The second category are errors that are caused by systems crashes. The latter case can be solved by restarting the system in the last consistent system state.
Re-execution of Workitems
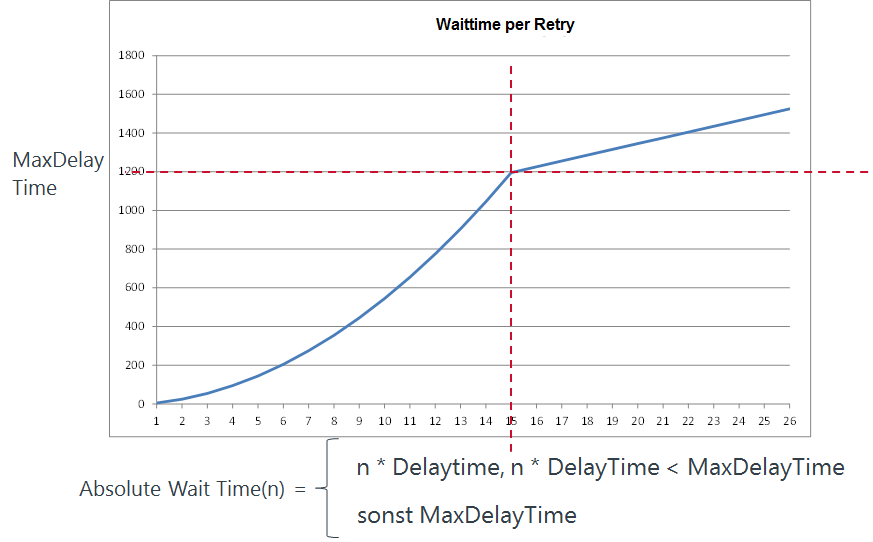
Whenever the execution of a workitems fails, Orchestra tries to solve the error by re-executing the workitem. The basic assumption relies on the fact that most type of errors can be solved by waiting and re-executing the workitem. This is true for all categories of technical errors like network and database errors. When an error occurs, Orchestra waits a specific amount of time and re-executes the workitem. In the case that the re-execution also fails, Orchestra waits a little bit longer until the next retry occurs. Since it is not useful to execute a workitem in an infinite loop, Orchestra stops the re-execution after a certain number of retries. A final error is sent to the owning subsystem.
The mechanism of re-execution is given in the following diagram:
System Crashes
System crashes should occur rarely, but when the occur the system should start up in the last valid state. In order to realize this requirement, Orchestra has to maintain state information in a persistent store. All state information that is necessary for a restart is given in the following enumeration:
-
process state
-
workqueue state
-
message data
The given state information is used when a system restart occurs. The workqueue state ensures that the work is processed exactly in the state that was given before the crash. Since a workitem normally requires information about process instances and message data this data is also used for a system restart and therefor has to be stored. Volatile process instances are not recoverable, since the volatile state information will be lost during a server crash. Process of type "volatile with recovery" are treated a little bit different. For each process instance of this category, the start information is stored persistent. This information contains mainly the start state and the associated data. When a system restart occurs, the list of running processes is computed. All running process will be restarted again from the beginning.